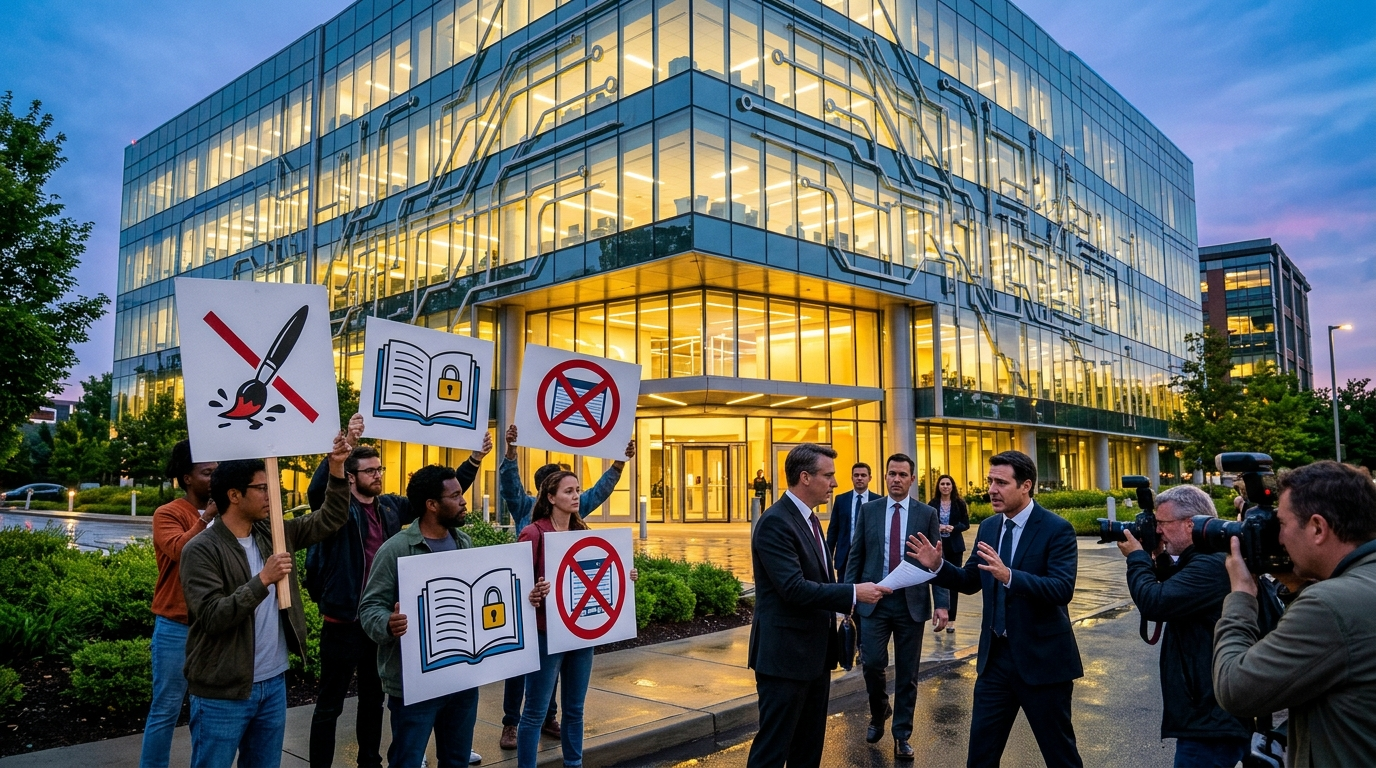
An AI company is facing another copyright infringement lawsuit, adding fresh pressure over how artificial intelligence systems obtain and use protected work. The available account does not identify the company, plaintiffs, court, or filing date. Still, its description as the latest case points to a growing legal dispute between AI developers and content owners.
The lawsuit centers on copyright, but its specific claims have not been disclosed. Key questions may include whether protected material was copied, used for AI training, or reproduced through generated results.
“It’s just the latest copyright infringement lawsuit brought against the AI company.”
That wording also indicates the company has faced earlier claims. Without court records or statements from the parties, however, the number and status of those cases remain unclear.
Copyright Disputes Follow AI Growth
Generative AI systems learn patterns from large collections of text, images, music, video, or software code. Content owners have argued in several cases that developers used their work without permission or payment.
AI companies have often answered that training does not store works in the same way as a traditional archive. Some also argue that analyzing material to identify patterns can qualify as fair use under United States law.
Courts must weigh those arguments against the rights granted to copyright holders. Those rights generally cover reproduction, distribution, public display, and the creation of adapted works.
The legal test depends on the facts of each case. Judges may examine what material was used, how it was obtained, and whether an AI product harms the market for the original work.
Missing Details Limit Early Conclusions
The brief account leaves several central facts unanswered:

- Which AI company has been sued
- Who filed the complaint
- What copyrighted works are involved
- Which court will hear the case
- What damages or restrictions are requested
Those details will determine the lawsuit’s scale and possible impact. A claim involving model training could challenge data collection practices. A case focused on generated output may instead test whether users or developers bear responsibility.
The distinction matters because AI products involve several parties. Developers build the models, businesses offer access, and users provide instructions. Courts may need to decide which party caused any unlawful copying.
Costs Could Reach Across the Industry
Repeated lawsuits can raise costs even before judges issue final rulings. AI developers may need to preserve training records, review data sources, negotiate licenses, or add stronger controls against close reproduction.
Publishers, artists, writers, and other rights holders also face difficult choices. Litigation can be expensive, while licensing agreements may offer faster compensation. Yet licenses may favor larger organizations that can negotiate at scale.
Consumers and businesses could also feel the effects. Tighter data rules may limit some AI features or increase prices. Clearer licensing systems, however, could give creators more control and reduce uncertainty for developers.
Courts May Shape Future AI Rules
The case joins a broader policy debate over whether current copyright law can address generative AI. Legislatures may create new disclosure or licensing rules, but court decisions are already setting practical limits.
The next filings will be important. The complaint should identify the works at issue and explain the alleged infringement. The company’s response may show whether it disputes the facts, invokes fair use, or seeks dismissal.
For now, the lawsuit offers more evidence that copyright risk has become a lasting concern for AI businesses. Its wider importance will depend on the unnamed parties, the alleged conduct, and whether the court reaches a ruling that other cases can follow.