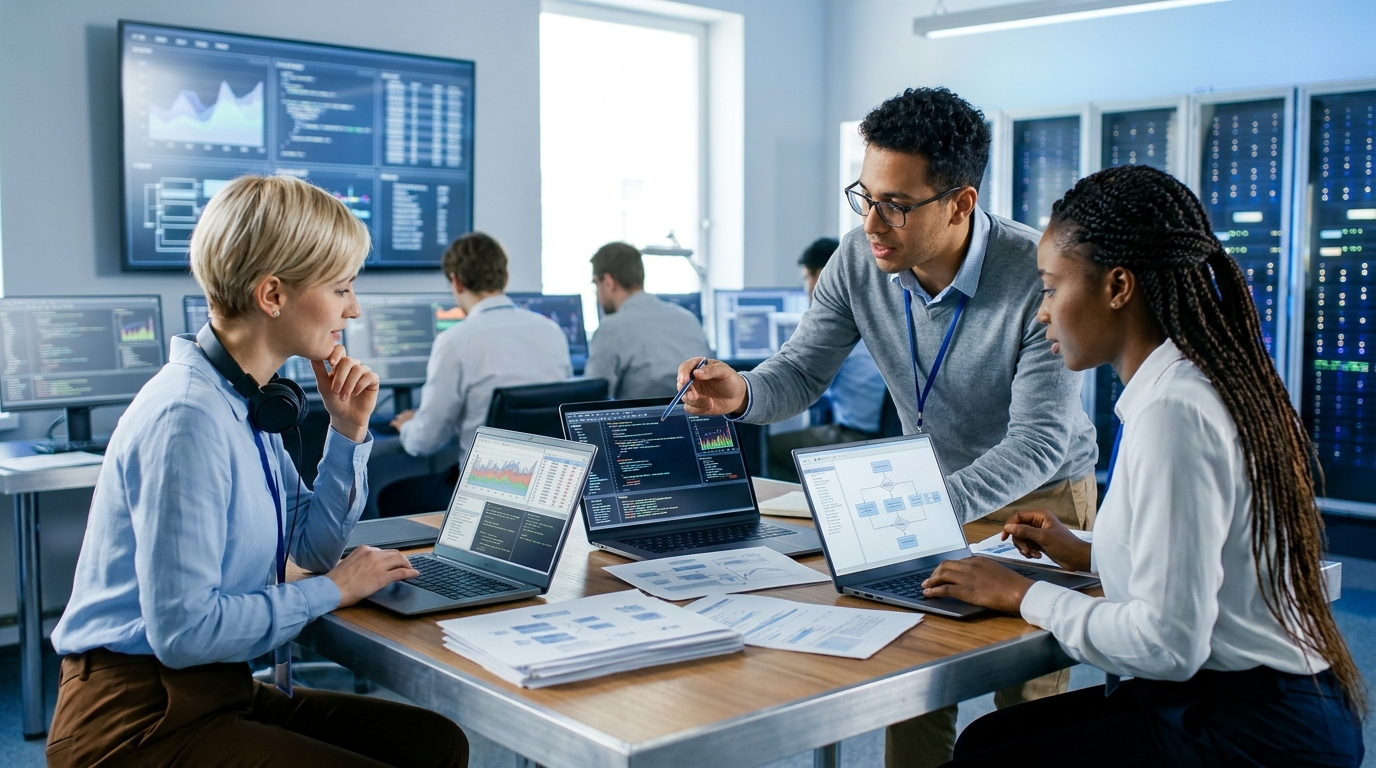
A short instruction, “See where multiple models agree,” points to a growing method for checking artificial intelligence outputs. Instead of trusting one system, users compare several models and examine where their answers match.
The approach can help researchers, journalists, businesses, and public agencies spot shared conclusions. Yet agreement alone does not prove that an answer is correct. Several models may repeat the same error, rely on similar source material, or interpret a prompt in the same flawed way.
Why Agreement Can Be Useful
AI models can produce different answers to the same question. Those differences may reflect training data, system design, safety rules, or how each service interprets the request.
Comparing outputs can reveal which claims appear stable across systems. If independent models reach similar conclusions and cite reliable evidence, confidence may increase. Disagreement can also be useful because it identifies claims that need closer review.
“See where multiple models agree.”
The instruction supports a simple review process. A user asks several models the same clearly written question, records their answers, and separates shared claims from disputed ones.
- Shared claims may deserve further verification.
- Conflicting claims require source checks.
- Missing evidence should reduce confidence.
- Matching citations should still be opened and reviewed.
Consensus Has Clear Limits
Model agreement can create false confidence. Many AI systems may have learned from overlapping websites, books, news reports, and public databases. They can therefore reproduce the same outdated statement or popular misconception.
Models may also copy patterns common in online writing. A claim repeated widely across the internet can appear credible even when its original source is weak.
The wording of a prompt creates another risk. A leading question can push several systems toward the same answer. Repeating the test with neutral language can show whether the apparent consensus is stable.
Agreement matters most when the models use different methods or sources. Even then, the result should be treated as a signal rather than a verdict.
A Stronger Verification Process
Users can improve the comparison by asking each model to explain its reasoning and identify sources. They should then check those sources directly, with special care for dates, authorship, and context.
High-stakes topics require added review. Medical, legal, financial, and public safety decisions should not rest on model consensus. Qualified professionals and primary documents remain necessary.
For current events, users should compare model responses with official records and recent reporting. AI systems may lack the latest information or may blend old and new details.
What Model Comparisons Actually Show
Cross-model testing is best viewed as an early screening tool. It can map areas of agreement, expose uncertainty, and guide human reviewers toward the claims most in need of attention.
The central lesson is practical: multiple matching answers are more informative than one answer, but they are not independent proof. The next step must be verification through credible evidence.
As more organizations use several AI systems at once, methods for measuring genuine independence will matter. Users should watch not only where models agree, but also why they agree and whether reliable sources support the result.