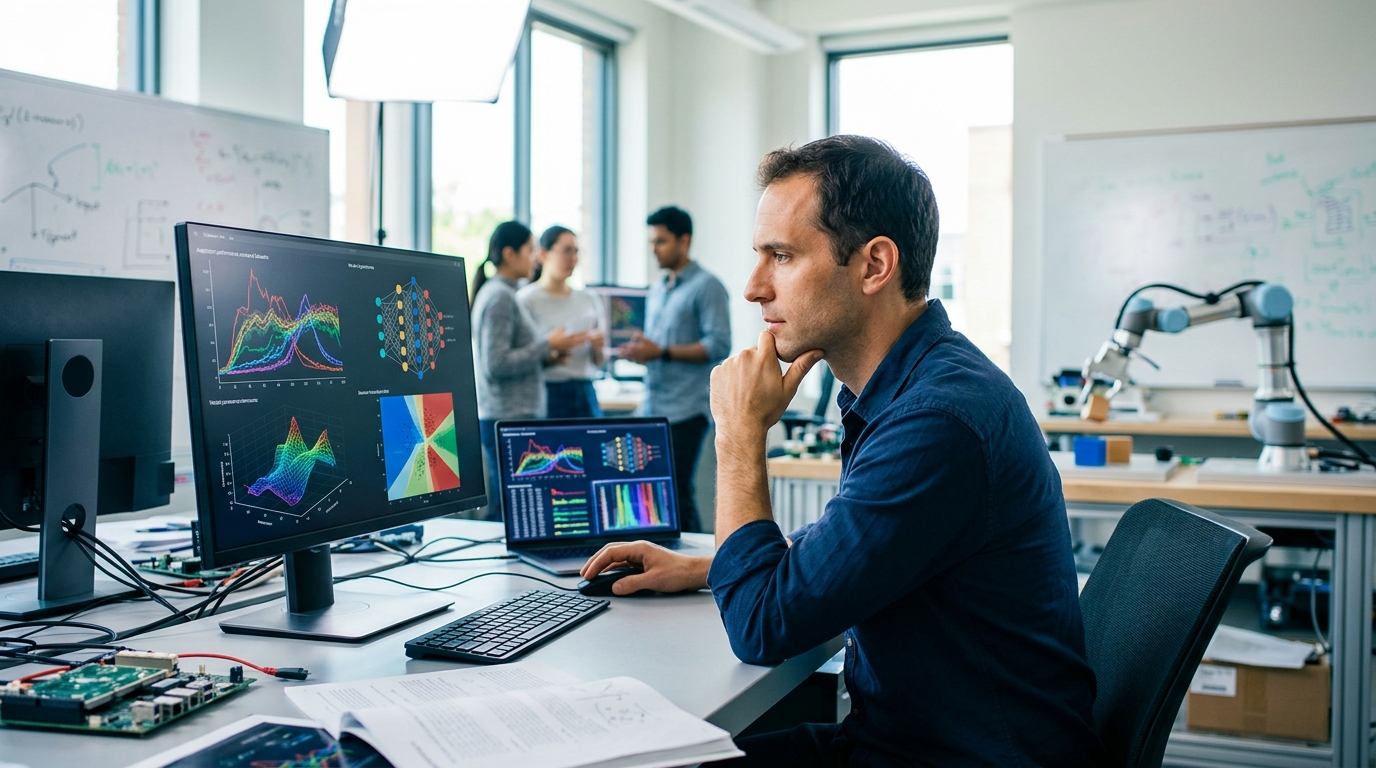
Sergey Levine examined how new algorithms could help machine learning systems remain selective while adapting to unfamiliar tasks and changing conditions.
The lecture focused on a central problem in artificial intelligence: systems need enough flexibility to learn, but also enough discernment to reject poor choices. Improving one trait can sometimes weaken the other.
Levine, a researcher known for work on machine learning and robotics, framed algorithm design as a search for balance. That balance matters for systems operating outside controlled training settings, where data may shift and mistakes may carry real costs.
Balancing Judgment and Flexibility
Machine learning models learn patterns from examples. Yet strong performance on training data does not guarantee sound decisions in a new setting.
A system that adapts too freely may absorb noise, follow misleading signals, or abandon useful prior knowledge. A rigid system may fail when conditions differ from its training experience.
The lecture examined algorithmic advances intended to preserve both abilities. In this context, discernment means distinguishing useful information from weak or harmful signals. Flexibility means adjusting behavior when new evidence warrants a change.
Several goals shape this area of research:
- Retaining useful knowledge while learning new tasks.
- Recognizing when new data differs from past experience.
- Avoiding harmful updates based on limited evidence.
- Adapting without losing reliable prior behavior.
Why the Trade-Off Matters
The tension has broad implications for robotics and automated decision systems. Robots may face new objects, rooms, or physical conditions after deployment. Software agents may also encounter data that differs from their original training set.

In those cases, fixed rules can limit performance. Unrestricted adaptation creates another risk. A system might become less reliable after learning from poor feedback or unusual examples.
Algorithms that retain judgment while adapting could support safer operation. They could also reduce the need to retrain a model from the beginning whenever its task changes.
However, flexibility alone is not proof of reliability. Researchers still need tests that measure behavior under rare events, shifting data, and incomplete feedback. Results from controlled experiments may not predict performance in open settings.
A Continuing Machine Learning Challenge
Levine’s focus reflects a long-running goal in artificial intelligence. Researchers want systems that can transfer knowledge from one task to another without applying old lessons blindly.
This challenge is closely tied to generalization, continual learning, and decision-making under uncertainty. Each area asks how a model should use prior experience while remaining responsive to new evidence.
Progress may depend on more than higher benchmark scores. Evaluation must show whether systems know when to adapt, when to preserve earlier knowledge, and when available evidence is too weak for action.
The lecture did not reduce the issue to a single measure or simple solution. Instead, its central theme pointed to a practical standard for future systems: adaptation should not come at the cost of judgment.
For researchers and developers, the next step is to test these methods under realistic changes and clear safety limits. The broader question is whether machine learning can become more adaptable while remaining dependable when conditions depart from the familiar.