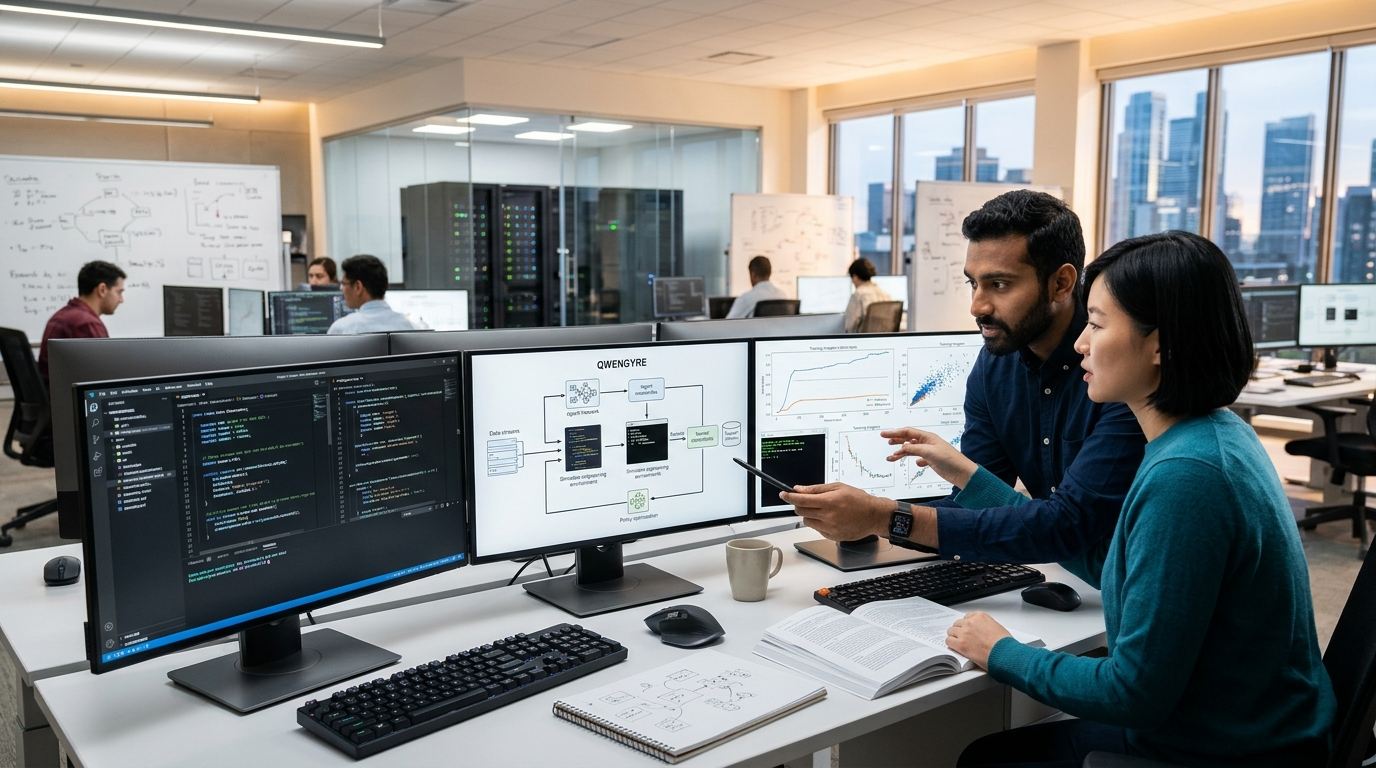
Alibaba’s Qwen researchers have detailed QwenGyre, a reinforcement learning framework designed to train AI agents on software engineering tasks that can last several hours.
The project targets a major weakness in current coding agents. Many systems can complete short, isolated requests, but struggle to remain effective during long assignments. QwenGyre seeks to train agents across these extended work periods while using computing resources more flexibly.
Training Agents for Longer Work
Software engineering rarely consists of one quick action. A developer may inspect a large codebase, trace a bug, edit several files, run tests, and revise the changes. Each step depends on earlier decisions.
QwenGyre focuses on these extreme-long horizon tasks. In AI research, a long-horizon task requires an agent to complete many linked actions before reaching a final result. Errors can build over time, making multi-hour assignments much harder than short coding tests.
Alibaba Qwen researchers described QwenGyre as “an elastic reinforcement learning framework” for training agents on “multi-hour software engineering tasks.”
Reinforcement learning trains a system through actions and feedback. For coding agents, useful signals may include whether tests pass, whether a patch fixes the stated problem, and whether the code remains stable. Multi-hour tasks complicate that process because rewards may arrive long after key decisions were made.
Why Elastic Training Matters
The term elastic suggests that QwenGyre can adjust how training work uses available computing capacity. That could matter because long agent sessions do not always consume resources at a steady rate.
An agent may alternate among model reasoning, code execution, testing, and waiting for tools. A fixed training setup can leave costly hardware idle during some stages while creating bottlenecks during others.
The framework’s stated focus points to three linked research goals:
- Keeping agents productive during assignments lasting several hours.
- Training from delayed feedback across long chains of actions.
- Managing computing resources as workloads change during a session.
These issues affect both research costs and practical performance. An agent that succeeds on a short benchmark may still fail during sustained work if it loses context, repeats steps, or cannot recover from an early mistake.
Higher Bar for Software Agents
Multi-hour training could support agents assigned larger jobs, such as resolving repository-wide bugs or carrying out complex code changes. Yet task duration alone does not prove that an agent works well.
Reliable evaluation would also need to measure correctness, security, test quality, and the amount of human oversight required. An agent could spend hours on a task and still produce a flawed patch. It might also optimize for passing visible tests while missing deeper requirements.
Longer autonomy creates additional risks. Agents may alter unrelated files, introduce hard-to-detect defects, or consume excessive computing time. Human review remains important, especially for production systems and sensitive code.
What Comes Next
QwenGyre reflects a wider shift from testing AI on brief coding questions to training systems for sustained technical work. The harder challenge is maintaining sound decisions across many tools, files, and feedback cycles.
Key questions will include how QwenGyre performs against other training methods, how much computing it requires, and whether its gains transfer across repositories and programming languages. Independent testing will also help establish whether success on multi-hour tasks leads to dependable results outside controlled evaluations.
Alibaba’s disclosure signals that long-duration agent training is becoming a central target for coding AI. Future results will show whether elastic reinforcement learning can make these agents more capable without sacrificing efficiency, safety, or human control.