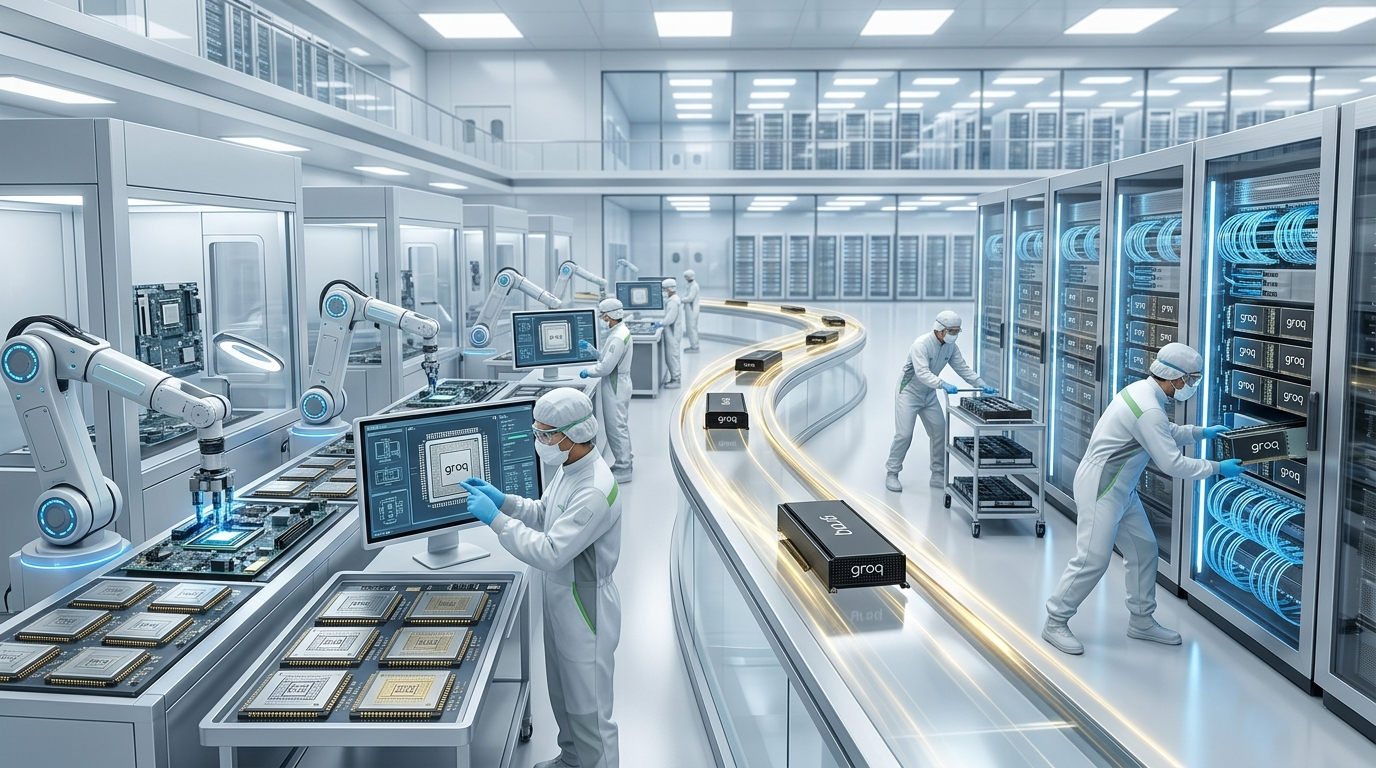
Nvidia is racing to manufacture Groq chips and place them with customers, signaling a sharper industry focus on low-latency artificial intelligence inference. The effort reflects rising demand for systems that can deliver AI-generated answers with little delay.
The race matters because inference is where trained AI models perform daily work. It includes answering questions, creating text, interpreting speech, and processing business data. Faster responses can improve services that depend on real-time decisions.
Inference Takes Center Stage
Much of the AI investment cycle has focused on training large models. Training requires major computing capacity and can take weeks or months. Inference begins after that work and often happens millions of times across a model’s operating life.
That difference has shifted attention to the cost and speed of serving users. A powerful model can still disappoint if each response arrives too slowly.
The manufacturing race highlights the growing importance of “low-latency inference” in AI.
Latency measures the delay between a request and a response. Low latency is valuable for voice assistants, automated customer support, coding tools, robotics, and other services where pauses can disrupt the user.
Speed also affects how many requests a system can handle. Chips designed for rapid inference may help operators support more users, although actual results depend on software, networking, model size, and energy use.
Nvidia Faces a Changing Market
Nvidia built its AI position around graphics processing units used for both model training and inference. Growing interest in Groq chips suggests customers are also examining processors designed around narrower AI workloads.
The manufacturing push could help Nvidia respond to demand while protecting its role in AI computing. Yet chip availability alone will not decide the outcome. Customers must consider purchase costs, operating expenses, software support, and compatibility with existing systems.
Groq’s focus on inference presents a different value case from general-purpose AI accelerators. Its appeal rests on predictable, rapid output for deployed models. That approach may gain support as companies move from AI trials to services used by employees and customers.
Customers Will Judge More Than Speed
Low latency is important, but it is only one measure of an inference system. Buyers are likely to assess several connected factors:
- Response time under normal and peak demand
- Cost for each processed request or generated token
- Energy use and cooling requirements
- Support for widely used models and software
- Supply levels and delivery schedules
A chip that performs well in a controlled test may produce different results in a working data center. Network delays, memory limits, and software design can affect the final user experience.
Reliability will also shape purchasing decisions. Businesses running medical, financial, industrial, or customer-facing systems need stable performance, not just brief bursts of speed.
Manufacturing Capacity Becomes Strategic
The effort to make Groq chips available points to another pressure in the AI sector: supply. Advanced processors require specialized production, packaging, testing, and delivery networks. Demand can rise faster than those systems can expand.
Manufacturing speed may therefore influence which chip designs gain wider adoption. Developers often build around hardware they can obtain at scale. Long delays can push customers toward rival products, even when their preferred chip offers better performance.
Nvidia’s race involving Groq chips shows that the next phase of AI competition will not rest only on training larger models. It will also depend on serving those models quickly, reliably, and at a workable cost.
The key test will be whether manufacturers can supply enough processors and whether customers see measurable gains in real operations. As AI services reach more users, inference speed and economics are likely to carry greater weight in technology budgets.